Outcome harvesting, and the workbook that looks right and isn’t.
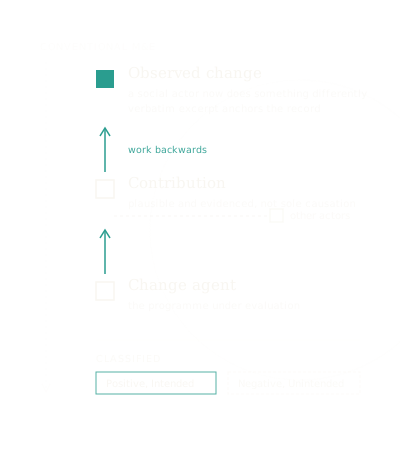
Outcome harvesting is one of the standard evaluation methodologies for capturing what actually changed as a result of a programme. Including outcomes the programme didn't set out to produce, and outcomes it produced without meaning to. The method was developed by Wilson-Grau and colleagues and remains the anchor for how the sector understands the approach.
The two ways an AI-assisted harvest goes wrong.
The failure modes here sit within two named categories. Technological incongruence is asking a model to do what it structurally cannot. Methodological incongruence is reproducing the surface procedure of the method (rows, classifications, a filled workbook) while stripping out the interpretive commitments that make the method valid.
Source fabrication is the technological incongruence. The model produces an outcome that reads plausibly, cites documents that exist, and references passages that were never actually written. It appears because the model is being asked to do something it structurally cannot do well: hold a long document pack in working memory and cite from it faithfully across many outputs.
Three structural controls, each answering a specific failure mode.
The candidate register answers source fabrication. Documents are read in chunks. Every candidate outcome the AI identifies is written to a structured register with a verbatim excerpt, the document it came from, and the location within the document. At the surfacing stage, a candidate is a question for the evaluator, not a claim; under-surfacing is the more expensive error than over-surfacing, because the evaluator can reject cheaply but cannot recover what was never shown. The workbook builder reads only from accepted register rows. The register also holds a rejection log, showing candidates that were surfaced and removed with the reasoning recorded, which is usually the strongest evidence of methodological rigour when a client asks whether alternative outcomes were considered.
The task split answers interpretive overreach. AI is assigned to the retrieval work. Reading document packs. Identifying passages that describe change. Extracting verbatim excerpts. Proposing classifications with reasoning. The interpretive judgements are reserved for the evaluator. Significance is drafted by the evaluator using AI-surfaced material as evidence, then confirmed with the client. Contribution plausibility is reasoned through by the evaluator, not generated. Classifications proposed by AI are confirmed rather than accepted. The line is drawn structurally in the tooling, not left to prompting discipline.
A workbook, a register, a rejection log, a disclosure.
Every Meridian outcome harvest produces four artefacts. The workbook, in the client's preferred format, with the six substantive columns populated and every source citation resolvable to a specific document and location. The candidate register, showing every candidate that was considered, its verbatim excerpt, and its disposition. The rejection log, showing candidates that were surfaced and removed with the reasoning recorded. The disclosure text, a short methodology annex drafted for inclusion in the evaluation report.
The disclosure text is not a legal disclaimer. It is a methodological statement, and its purpose is to let a reader of the report understand how the evidence was produced. Meridian believes this should be standard practice across the sector. It isn't yet.
The differentiation is the discipline.
Outcome harvesting stops being outcome harvesting the moment its interpretive commitments are stripped away and only the workbook rows remain. The register and rejection log preserve the interpretive audit trail. Substantiation runs through client review, not through agreement scores that would import a validation metric the method does not use. Meridian's workflow is built to keep the method recognisable as the method its originators developed.